R
• 통계 처리와그래픽을 위한 프로그래밍 언어
이자 소프트웨어 환경을 통칭
• S language의 free implementation
• 뉴질랜드 오클랜드(Auckland) 대학의 Ross
Ihaka와 Robert Gentleman 교수가 시작
• R Development Core Team에서 개발 진행
• SPSS나 SAS의 훌륭한 대안
• Bioinformatics, Finance, GIS 등등 많은 분야
에서 활용
8.
R의 장점
• 대화식프로그램 수행, 결과물의 객체화
• 자유로운 분석 환경 제공
• 사용자가 제작한 패키지 추가하여 기능 확장 가능
• 검증된 기능만을 제공하는 상용툴과는 달리 학계의 최신 연구
결과가 빠르게 반영됨
• 출판물 수준의 그래프를 제공할 수 있는 강력한 그래픽 기능
• 행렬 계산을 위한 막강한 도구
• 객체지향 방법론 지원
• 다양한 사용자 운영 환경 지원
– Windows, Unix/Linux, Mac 등 다양한 운영체제 지원
– Java, C, Fortran 등의 프로그래밍 언어와 연동 가능
– SAS, SPSS, Minitab 등의 데이터 및 DBMS 접근 용이
vector
> v1 <-c(1,2,3) # 숫자형 벡터 생성
> v1
[1] 1 2 3
> v2 <- c("a", "b", "c") # 문자형 벡터 생성
> v2
[1] "a" "b" "c"
> v3 <- c(T, F, T) # 논리형 벡터 생성
> mode(v1); mode(v2)
[1] "logical"
[1] "numeric"
> height <- c(160, 140, 155) # height 벡터 생성
> people <- c("Ned", "Jill", "Pat")
> names(height) <- people # height 벡터의 원소에 이름을 할당
> height
Ned Jill Pat
160 140 155
> height["Ned"]
Ned
160
> names(height) <- NULL # height 벡터의 원소의 이름을 삭제
> height
[1] 160 140 155
17.
vector
• 타입 변환
–Implicit Coercion : logical < numeric < character
– Explicit Coercion : as.* functions
> y <- c(1.7, "a") # character
> y <- c(TRUE, 2) # numeric
> y <- c("a", TRUE) # character
> x <- 0:6
> class(x)
[1] "integer"
> as.numeric(x)
[1] 0 1 2 3 4 5 6
> as.logical(x)
[1] FALSE TRUE TRUE TRUE TRUE TRUE TRUE
> as.character(x)
[1] "0" "1" "2" "3" "4" "5" "6"
18.
array
• 배열은 행렬을2차원 이상으로 확장시킨 객체이
다. 따라서 2차원의 구조를 갖는 행렬도 배열의
한 종류이다. 그러나 일반적으로 3차원 이상의
차원을 갖는 데이터 객체를 배열이라고 부른다.
19.
array
> arr <-array(1:24, c(3,4,2)) # 1~24까지의 자료를 (3X4X2) 차원으로 생성
> dimnames(arr) <- list(paste("row", c(1:3)),paste("col", c(1:4)),paste("array", c(1:2)))
> arr
… 생략 …
> length(arr) # 자료의 개수 확인
[1] 24
> mode(arr) # 자료의 형태 확인
[1] "numeric"
> dim(arr) # 각 차원 벡터의 크기
[1] 3 4 2
> dimnames(arr) # 각 차원 리스트의 이름
[[1]]
[1] "row 1" "row 2" "row 3"
[[2]]
[1] "col 1" "col 2" "col 3“ "col 4"
[[3]]
[1] "array 1" "array 2"
20.
array
> array(1:6) #1~6의 자료로 1차원 배열 생성
[1] 1 2 3 4 5 6
> array(1:6, c(2,3)) # 1~6의 자료로 2차원 배열 생성
[,1] [,2] [,3]
[1,] 1 3 5
[2,] 2 4 6
> array(1:8, c(2,2,2)) # 1~8의 자료로 3차원 배열 생성
, , 1
[,1] [,2]
[1,] 1 3
[2,] 2 4
… 생략 …
> arr <- c(1:24) # 1~24의 자료 생성
> dim(arr) <- c(3,4,2); arr # dim() 함수를 이용하여 3행 4열의 행렬 2개 생성
, , 1
[,1] [,2] [,3] [,4]
[1,] 1 4 7 10
[2,] 2 5 8 11
[3,] 3 6 9 12
21.
list
• 리스트(list)는 서로다른 형태(mode)의 데이터들로 구성
된 객체이다. 리스트는 성분(component)이라는 것으로
이루어지는데 이 성분들은 서로 다른 형의 원소를 가질
수 있고, 길이도 다를 수 있다. 성분은 행렬과 배열의 차
원과 유사하다.
• 리스트에서의 성분을 추출하는 방법은 [[]] 를 사용하며,
성분의 이름을 지정하였다면 $ 연산자를 사용한다.
22.
list
> li <-list("top", c(2,4,6), c(T,F,T)) # list(문자, 숫자, 논리형 객체)
> li
… 생략 …
> li[[1]] # [[1]]:첫 번째 성분
[1] "top"
> son <- list(son.name = c("Minsu", "Minchul"), son.cnt = 2, son.age = c(2, 6))
> son
$son.name
[1] "Minsu" "Minchul"
$son.cnt
[1] 2
$son.age
[1] 2.6
> names(son)
[1] "son.name" "son.cnt" "son.age"
> length(son)
[1] 3
data frame
• 행렬과비슷한 형태로 되어 있으나, 행렬은 차원으로 표
시되며 같은 형태(mode)의 객체를 가지는 반면, 데이터
프레임은 각 열(column)들이 서로 다른 형태(mode)의
객체를 가질 수 있다.
• 각 요소가 행렬의 열 벡터에 해당하는 리스트이다.
• 데이터 프레임의 장점
– 데이터 프레임은 형태(mode)가 일반화된 행렬(matrix)이다.
– 데이터 프레임이라는 하나의 객체에 여러 종류의 자료가 들어갈 수 있
다.
– 데이터 프레임의 각 열은 각각 변수와 대응한다.
– 분석이나 모형 설정에 적합한 자료 객체이다.
25.
data frame
• 생성방법
– read.table() 함수를 이용하여 외부 텍스트 파일을 불
러들이는 방법
– data.frame() 함수를 이용하여 여러 종류의 자료객체
들을 서로 결합시키는 방법
– as.data.frame() 함수를 사용하여 다른 형태의 자료객
체를 데이터 프레임의 형태로 변환하는 방법
26.
data frame
> test1<- read.table("./story.txt")
> test1
V1 V2 V3 V4
1 no name age sex
2 1 Lee 55 M
3 2 Park 47 F
4 3 So 35 M
5 4 Kim 26 F
6 5 Yoon 29 M
> test2 <- read.table("./story.txt", row.names='no', header=T)
> test2
name age sex
1 Lee 55 M
2 Park 47 F
3 So 35 M
4 Kim 26 F
5 Yoon 29 M
27.
data frame
> char1<- rep(LETTERS[1:3],c(2,2,1)) # 벡터 char1
> num1 <- rep(1:3,c(2,2,1)) # 벡터 num1
> test1 <- data.frame(char1, num1) # test1 데이터 프레임 생성
> test1
char1 num1
1 A 1
2 A 1
3 B 2
4 B 2
5 C 3
> a1 <- c("a","b","c","d","e","f","g","h","i","j","k","l","m","n","o")
> dim(a1) <- c(5,3)
> a1
[,1] [,2] [,3]
[1,] "a" "f" "k"
[2,] "b" "g" "l"
[3,] "c" "h" "m"
[4,] "d" "i" "n"
[5,] "e" "j" "o"
> test3 <- as.data.frame(a1) # a1을 데이터 프레임으로 변환
> test3
V1 V2 V3
1 a f k
2 b g l
3 c h m
4 d i n
5 e j o
28.
data frame
• dataframe 합치기
– cbind() : 데이터 프레임을 옆으로 합친다.
– rbind() : “ 아래로 합친다.
– merge() : join과 유사
> cbind(test1,test3) # test1과 test2를 옆으로 합친 형태
char1 num1 V1 V2 V3
1 A 1 a f k
2 A 1 b g l
3 B 2 c h m
4 B 2 d i n
5 C 3 e j o
29.
factor
• 팩터는 범주형데이터를 표현하는데 사용된다.
– ordered/unorderd factor 사용 가능
• 각 integer 값을 label로 가지는 integer vector로 볼 수
있다.
• Self-describing 특성을 가지므로 integer보다 좋다.
– Male/Female vs. 1/2
30.
factor
> x <-c("A", "B", "C", "B", "A")
> factor(x)
[1] A B C B A
Levels: A B C
> table(x) # 각 자료 범주의 도수를 요약해서 보여준다.
x
A B C
2 2 1
> final <- c(45, 90, 82, 76, 79)
> grades=cut(final,breaks=c(0,60,80,100)) # 수치형 자료의 범주화
> grades
[1] (0,60] (80,100] (80,100] (60,80] (60,80]
Levels: (0,60] (60,80] (80,100]
> levels(grades)=c("C","B","A")
> grades
[1] C A A B B
Levels: C B A
> table(grades)
grades
C B A
1 2 2
연습!!
• 180, 175,168, 173, 165를 원소로 갖는 height 벡터를 생
성하고, 각각의 원소에 LEE, KIM, PARK, KANG, SONG의
이름을 할당하시오.
• 10, 15, 2, 8, 20의 자료를 원소로 갖는 vec 벡터를 생성
하고,
– 2, 3, 5번째 자료를 추출
– 2, 3번째 자료를 제거
• 1~100까지의 범위 내에서 5의 간격을 갖는 값들을 생성
하고, 생성한 자료를 역순으로 나타내시오.
• 1~8, 11~18, 111~118로 이루어진 2, 4, 3차원의 배열을
만드시오.
• 저장된 array 데이터 iris3의 (38,4,1)번째 원소를 추출하
시오.
33.
matrix
• 행렬은 동일한형으로 구성된 2차원의 데이터 구조다. 행
의 차원과 열의 차원을 갖는 행렬은 수학에서의 행렬과
는 달리 문자형이나 논리형 등을 원소로 사용할 수 있다.
그러나 행렬의 원소는 한가지 형의 자료만 허락된다.
34.
matrix
• 메트릭스는 차원attribute를 가진 특수한 벡터라고 볼 수 있다.
• 벡터에 dimension attribute를 추가하여 메트릭스를 생성할 수 있다.
> m <- matrix(nrow = 2, ncol = 3)
> dim(m)
[1] 2 3
> attributes(m)
$dim
[1] 2 3
> m <- 1:10
> m
[1] 1 2 3 4 5 6 7 8 9 10
> dim(m) <- c(2, 5)
> m
[,1] [,2] [,3] [,4] [,5]
[1,] 1 3 5 7 9
[2,] 2 4 6 8 10
35.
matrix
> matr <-matrix(1:9, nrow=3) # 3행 3열 행렬 생성
> dimnames(matr) <- list(paste("row", c(1:3)), paste("col", c(1:3))) # 행과 열 이름 지정
> matr
col 1 col 2 col 3
row 1 1 4 7
row 2 2 5 8
row 3 3 6 9
> length(matr) # 자료의 개수
[1] 9
> mode(matr) # 자료의 형태
[1] "numeric"
> dim(matr) # 행과 열의 개수
[1] 3 3
> dimnames(matr) # 행과 열의 이름 확인
[[1]]
[1] "row 1" "row 2" "row 3"
[[2]]
[1] "col 1" "col 2" "col 3"
matrix (apply)
> height<- c(140,155,142,175) # height 벡터 생성
> size.1 <- matrix(c(130,26,110,24,118,25,112,25), ncol=2, byrow=T,
+ dimnames=list(c("Abe", "Bob", "Carol", "Deb"), c("Weight", "Waist"))) # size.1 행렬 생성
> size <- cbind(size.1, height) # size.1 행렬과 height 벡터의 열 기준 결 합
> size
Weight Waist height
Abe 130 26 140
Bob 110 24 155
Carol 118 25 142
Deb 112 25 175
> colmean <- apply(size, 2, mean) # MARGIN 2 : 열의 평균값을 계산
> colmean
Weight Waist height
117.5 25.0 153.0
> rowmean <- apply(size, 1, mean) # MARGIN 1 : 행의 평균값을 계산
> rowmean
Abe Bob Carol Deb
98.66667 96.33333 95.00000 104.00000
> colvar <- apply(size, 2, var)
> rowsum <- apply(size, 1, sum)
39.
행렬 연산
> C<- matrix(c(1,2,3,4,5,6,7,8,9),nrow=3)
> D <- matrix(c(1,2,3,4,5,6,7,8,9),nrow=3,byrow=T)
> E <- matrix(c(1,2,3,4,5,6),nrow=2)
> F <- matrix(c(1,2,3,4,5,6),nrow=3,byrow=T)
> F <- t(E) # transpose
> C %*% D # multiplication
자료 객체 정리
자료객체 구성 차원 자료 유형(mode) 여러 유형
벡터 1차원 수치/문자/복소수/논리 불가능
행렬 2차원 수치/문자/복소수/논리 불가능
데이터 프레임 2차원 수치/문자/복소수/논리 가능
배열 2차원 이상 수치/문자/복소수/논리 불가능
요인 1차원 수치/문자 불가능
시계열 2차원 수치/문자/복소수/논리 불가능
리스트 2차원 이상 수치/문자/복소수/논리/
함수/표현식/call 등
가능
출처 : 기초 자료 분석을 위한 R 입문
확률 분포
• 정규분포
>x<-rnorm(1000) # 표준정규분포 샘플 1000개 생성
> hist(x, freq=F) # freq=F : 빈도가 아닌 밀도
> curve(dnorm(x),add=T) # add=T : 그림을 겹쳐 그린다
> qnorm(0)
[1] -Inf
> qnorm(0.5)
[1] 0
> qnorm(1)
[1] Inf
> pnorm(0)
[1] 0.5
46.
확률 분포
• 이항분포
># 동전을 40번 던졌을 때 앞면이 나올 횟수에 대한 확률
> # require(graphics)
> n<-40
> k<-seq(0,n,by=1)
> plot (k, dbinom(k, n, 1/2))
> lines(k, dbinom(k, n, 1/2), col='red’)
그래프
• 3차원 산점도
install.packages("rgl")# R에서 OpenGL 기능을 쓸 수 있게 해주는 패키지
library(rgl)
x <- sort(rnorm(1000))
y <- rnorm(1000)
z <- rnorm(1000) + atan2(x,y)
plot3d(x, y, z, col=rainbow(1000), size=2)
rgl.snapshot("test.png") #
복습
특수 형태의 데이터
-NA : Not Available / Missing Values
- NaN : Not a Number
- Inf, -Inf : positive and negative infinity
> x <- c(1,2,3,4,5,6,7,8,9)
> y <- x
> y[c(2,4,6,8)] <- 0
> y == 7
[1] FALSE FALSE FALSE FALSE FALSE FALSE TRUE FALSE FALSE
> which(y==0)
[1] 2 4 6 8
> x+y
[1] 2 2 6 4 10 6 14 8 18
> x-y
[1] 0 2 0 4 0 6 0 8 0
> x <- c(x,10,11,12)
> x[14:16] <- c(14:16)
> x
[1] 1 2 3 4 5 6 7 8 9 10 11 12 NA 14 15 16
63.
복습
> ast <-function(x) { # 함수 이름, 함수 인자
+ for(i in 1:x) print(rep('*',i)) # 함수 몸체
+ x+1 # 함수 리턴값
+ }
> ret <- ast(3)
[1] "*"
[1] "*" "*"
[1] "*" "*" "*"
> ret
[1] 4
> li <- list("test", c(1:3), c(LETTERS[1:3])) # 여러 타입에 대해서
> for(c in li) print(c) # 반복문을 수행할 수 있다.
[1] "test"
[1] 1 2 3
[1] "A" "B" "C"
64.
복습
> data <-matrix(x[5:16], ncol=4); data
[,1] [,2] [,3] [,4]
[1,] 5 8 11 14
[2,] 6 9 12 15
[3,] 7 10 NA 16
> apply(data, 1, sum) # array 또는 matrix에 대해 MARGIN 적용하여 함수 적용
[1] 38 42 NA
> apply(data, 2, sum)
[1] 18 27 NA 45
> apply(data, 1, sum, na.rm=T) # na.rm=T를 입력해서 NA 데이터는 제외
[1] 38 42 33
> lapply(women[,c(1,2)], mean) # list 또는 vector에 대해 함수 적용하여 list 반환
$height
[1] 65
$weight
[1] 136.7333
> sapply(c(1,2,3,4), function(x) x^2) # sapply는 lapply의 간단(?) 버전
[1] 1 4 9 16
> sapply(women[,c(1,2)], mean)
height weight
65.0000 136.7333
65.
복습
> my_women <-cbind(women, type=rep(LETTERS[1:3], 5)); my_women
height weight type
1 58 115 A
2 59 117 B
... 생략 …
14 71 159 B
15 72 164 C
> tapply(my_women$weight, my_women$type, mean) # factor로 그룹화, table 형태로 출력
A B C
133.2 136.6 140.4
> my_women <- cbind(my_women, label=c(rep(0,7), rep(1,8))); my_women
height weight type label
1 58 115 A 0
2 59 117 B 0
… 생략 …
14 71 159 B 1
15 72 164 C 1
> tapply(my_women$weight, my_women[c(3,4)], mean)
label
type 0 1
A 123.3333 148.0000
B 121.5000 146.6667
C 124.5000 151.0000
66.
목차
• R의 패키지관리 및 응용
• 대용량 데이터 관련 패키지 소개
• Hadoop 에코 시스템을 활용한 R의 빅데
이터 분석
67.
패키지와 CRAN
• 패키지: 특정 목적을 위해 함수들로 구현
된 복잡한 R 명령어와 데이터들의 집합
• CRAN(Comprehensive R Archive Network)
– network of ftp and web servers around the
world that store identical, up-to-date,
versions of code and documentation for R
– http://cran.r-project.org/
패키지 설치/사용/제거
• search()
–attach된 package들과 R objects(usually dataframe) 확인
• searchpaths()
– 패키지들이 설치된 path 확인
• chooseCRANmirror()
• setRepositories()
• library()
– 패키지를 load하는 명령
• detach()
– 패키지나 데이터프레임의 검색 경로 등록을 취소
• install.packages()
• remove.packages()
• update.packages()
70.
패키지 설치/사용/제거
> utils::install.packages('qcc')
>search()
[1] ".GlobalEnv" "package:MASS" "package:stats"
[4] "package:graphics" "package:grDevices" "package:utils"
[7] "package:datasets" "package:methods" "Autoloads"
[10] "package:base"
> library('qcc')
Package 'qcc', version 2.2
Type 'citation("qcc")' for citing this R package in publications.
> search()
[1] ".GlobalEnv" "package:qcc" "package:MASS"
[4] "package:stats" "package:graphics" "package:grDevices"
[7] "package:utils" "package:datasets" "package:methods"
[10] "Autoloads" "package:base"
71.
패키지 설치/사용/제거
> detach("package:qcc")
>search()
[1] ".GlobalEnv" "package:MASS" "package:stats"
[4] "package:graphics" "package:grDevices" "package:utils"
[7] "package:datasets" "package:methods" "Autoloads"
[10] "package:base"
> utils::remove.packages('qcc')
Removing package(s) from ‘/usr/lib64/R/library’
(as ‘lib’ is unspecified)
Updating HTML index of packages in '.Library'
Making packages.html ... done
>
72.
작업공간
• object
– 변수(variables),데이터(data, dataset), 함수(functions),
결과(results)처럼 메모리(작업공간)에 특정 이름으로
저장되는 것을 의미
• data frame(=data set, data matrix), data file
– 특수한 형태의 리스트로서 "data.frame" 라는 클래스
로 따로 구분. 파일 형태로 저장되면 datafile
• database
– data.frame, list, R data file, NULL, environment, …
• workspace
– The collection of objects currently stored
73.
작업공간
• save.image() :.RData에 작업공간 저장
• savehistory() : .Rhistory에 명령어 history 저장
• load() : 작업공간 로드
• loadhistory() : 명령어 history 로드
> x <- 5
> ls()
[1] "x"
> save.image()
> savehistory()
> rm(list=ls())
> ls()
character(0)
> load(".RData")
> ls()
[1] "x"
74.
패키지 built-in 데이터사용
> data()
> library(qcc)
> data(package = "qcc")
> data(pcmanufact)
> ls()
> pcmanufact
x size
1 10 5
2 12 5
[root@localhost data]# ls -l /usr/lib64/R/library/qcc/data
합계 56
-rw-r--r-- 1 root root 305 2월 21 20:43 boiler.txt.gz
-rw-r--r-- 1 root root 155 2월 21 20:43 circuit.txt.gz
-rw-r--r-- 1 root root 77 2월 21 20:43 dyedcloth.txt.gz
-rw-r--r-- 1 root root 246 2월 21 20:43 orangejuice.txt.gz
-rw-r--r-- 1 root root 258 2월 21 20:43 orangejuice2.txt.gz
-rw-r--r-- 1 root root 71 2월 21 20:43 pcmanufact.txt.gz
-rw-r--r-- 1 root root 607 2월 21 20:43 pistonrings.txt.gz
…
75.
데이터 attach/detach
• attach/detach
–database(데이터프레임, R data file, …)를 R 검색 경로에 at/detach 시킴
• ls/rm
– 명시된 환경에서의 object 리스트를 출력/제거
> search()
[1] ".GlobalEnv" "package:stats" "package:graphics“
[4] "package:MASS" "package:stats" "package:graphics"
> x
에러:오브젝트 'x'가 없습니다
> size
에러:오브젝트 'size'가 없습니다
> library(qcc)
> x <-5
> x
[1] 5
R script
• Rscript명령 사용
• stdin에서 파일 redirect
• source( ) 함수 사용
# vi test.R
x <- c(1,2,4)
print(mean(x))
# Rscript test.R
[1] 2.333333
# R --no-save < test.R # redirect
# R
> source(‘test.R’)
[1] 2.333333
79.
R과 빅데이터
• R에서빅 데이터 분석이 힘든 이유
– 기본 빌드된 R에서는 단일 코어만 사용
• 멀티 코어 활용할 수 있는 패키지 사용
• 2.14 버전부터는 일부 함수들이 멀티코어 활용
– 메모리 한계 이슈
• R의 허용 메모리 사용량 제약
• 모든 데이터를 메모리에 로딩 후 처리하는 방식
• int64 같은 64비트 최적화 자료형 미지원
big* 패키지
• bigmemory
–create, store, access, and manipulate massive
matrices.
– matrices are allocated to shared memory
and may use memory-mapped files.
• biganalytics
– this package extends the bigmemory
package with various analytics.
– summary, bigkmeans, apply for big.matrix
objects.
83.
bigmemory
> install.packages(“bigmemory”)
> library(bigmemory)
bigmemory>= 4.0 is a major revision since 3.1.2; please see package
biganalytics and http://www.bigmemory.org for more information.
> x <- big.matrix(5, 2, type="integer", init=0, dimnames=list(NULL, c("alpha", "beta")))
> x
An object of class "big.matrix"
Slot "address":
<pointer: 0x459a790>
> x[1:2,]
alpha beta
[1,] 0 0
[2,] 0 0
> x[,1] <- 1:5
> x[,"alpha"]
[1] 1 2 3 4 5
> colnames(x)
[1] "alpha" "beta"
> options(bigmemory.allow.dimnames=TRUE)
> colnames(x) <- NULL
> x[,]
RHadoop
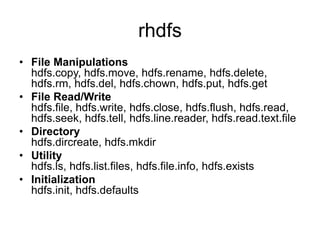
• Collection ofthree R packages that allow users
to manage and analyze data with Hadoop.
• RHadoop consists of the following packages:
– rmr - functions providing Hadoop MapReduce
functionality in R
– rhdfs - functions providing file management of the
HDFS from within R
– rhbase - functions providing database management
for the HBase distributed database from within R
86.
RHadoop 설치(rhdfs)
# su- # RHadoop 패키지 설치 작업은 root 계정으로
# curl -L https://github.com/RevolutionAnalytics/rhdfs/blob/master/build/rhdfs_1.0.8.tar.gz?raw=true -o rhdfs.tar.gz
# export JAVA_HOME=/usr/local/jdk-<version> # 환경변수는 각자 환경에 맞게 수정할 것!
# R CMD javareconf
# R
> install.packages(“rJava”)
> q()
# export HADOOP_HOME=/home/hadoop/hadoop
# export HADOOP_CMD=$HADOOP_HOME/bin/hadoop
# export HADOOP_STREAMING=$HADOOP_HOME/contrib/streaming/hadoop-streaming-<version>.jar
# R CMD INSTALL rhdfs.tar.gz # 단, Hadoop이 실행중인 상태에서 설치해야함
87.
RHadoop 설치(rmr)
# su- # RHadoop 패키지 설치 작업은 root 계정으로
# curl -L http://goo.gl/dvBric -o rmr2.tar.gz
# export JAVA_HOME=/usr/local/jdk-<version> # 환경변수는 각자 환경에 맞게 수정할 것!
# export HADOOP_HOME=/home/hadoop/hadoop
# export HADOOP_CONF=$HADOOP_HOME/conf
# export HADOOP_CMD=$HADOOP_HOME/bin/hadoop
# export HADOOP_STREAMING=$HADOOP_HOME/contrib/streaming/hadoop-streaming-<version>.jar
# R
> install.packages(c(‘Rcpp’, ‘RJSONIO’, ‘itertools’, ‘digest’, ‘functional’, ‘stringr’, ‘plyr’))
> # 필요하면 bitops, reshape2, caTools 같은 패키지들도 추가로 설치
> q()
# R CMD INSTALL rmr2.tar.gz # 단, Hadoop이 실행중인 상태에서 설치해야함
Rhadoop 예제 (wordcount)
>file = to.dfs("I saw a saw saw a saw in a saw.", format="text")
> out = wordcount(file)
packageJobJar: [/tmp/RtmpSJ73OT/rhstr.map1a0966bb8d5a,
/tmp/RtmpSJ73OT/rhstr.reduce1a09315feee9, /tmp/RtmpSJ73OT/rhstr.combine1a091a3a4826,
/tmp/RtmpSJ73OT/rmr-local-env, /tmp/RtmpSJ73OT/rmr-global-env, /tmp/hadoop-hadoop/hadoop-
unjar4399993970582808045/] [] /tmp/streamjob7923541988067611842.jar tmpDir=null
… 중략 …
12/06/04 18:16:48 INFO streaming.StreamJob: /usr/local/hadoop/hadoop-1.0.2/libexec/../bin/hadoop
job -Dmapred.job.tracker=cudatest:9001 -kill job_201206012240_0014
12/06/04 18:16:48 INFO streaming.StreamJob: Tracking URL:
http://cudatest:50030/jobdetails.jsp?jobid=job_201206012240_0014
12/06/04 18:16:49 INFO streaming.StreamJob: map 0% reduce 0%
12/06/04 18:17:02 INFO streaming.StreamJob: map 50% reduce 0%
12/06/04 18:17:05 INFO streaming.StreamJob: map 100% reduce 0%
12/06/04 18:17:11 INFO streaming.StreamJob: map 100% reduce 33%
12/06/04 18:17:17 INFO streaming.StreamJob: map 100% reduce 100%
12/06/04 18:17:23 INFO streaming.StreamJob: Job complete: job_201206012240_0014
12/06/04 18:17:23 INFO streaming.StreamJob: Output: /tmp/RtmpSJ73OT/file1a096787a771
> result = from.dfs(out); result
> # out = wordcount("/user/hadoop/input/README.txt")
96.
Rhadoop 예제 (k-means)
•K-means Clustering : 무작위로 선정된 k개의 중심점(centroid)을
선정하고 이 점에서 가장 근접한 항목들을 할당하면서 시작. 할
당 후에는 할당된 모든 노드들의 평균 위치로 중심점을 이동시키
고 재할당을 수행한다. 할당이 더 이상 없을 때까지 이 과정을 반
복한다.
#34 Matrices are vectors with a dimension attribute. The dimension attribute is itself an integer vector of length 2 (nrow, ncol) Matrices can also be created directly from vectors by adding a dimension attribute.


![factor
> x <- c("A", "B", "C", "B", "A")
> factor(x)
[1] A B C B A
Levels: A B C
> table(x) # 각 자료 범주의 도수를 요약해서 보여준다.
x
A B C
2 2 1
> final <- c(45, 90, 82, 76, 79)
> grades=cut(final,breaks=c(0,60,80,100)) # 수치형 자료의 범주화
> grades
[1] (0,60] (80,100] (80,100] (60,80] (60,80]
Levels: (0,60] (60,80] (80,100]
> levels(grades)=c("C","B","A")
> grades
[1] C A A B B
Levels: C B A
> table(grades)
grades
C B A
1 2 2](/proxy?url=https%3A%2F%2Fimage.slidesharecdn.com%2Frintro-120823043618-phpapp02%2F85%2FR-intro-30-320.jpg)